
Key takeaways
- AI developers want accurate, specific, legally clean data. Public web text is finite and increasingly restricted, so private data with clear rights is more attractive.
- Public evidence of demand is strongest for expert-written work, code and simulated workspaces. We found no public source naming a buyer or price for an ordinary company's raw support tickets or CRM exports.
- Price figures in the press are reported, usually from anonymous sources, and mix annual fees, contract totals and segment revenue. Treat them as context, not a quote for your data.
- The biggest blocker is rights: customer contracts, privacy promises, employee data, recorded calls and open-source licenses decide what you can sell.
- De-identification lowers risk but does not remove it. Re-identification has repeatedly succeeded on data thought to be anonymous.
- Read the deal terms, not just the price: exclusivity, field of use, deletion, audit and indemnity decide what you have actually sold.
The short answer#
Yes, companies can sell or license their own business data to AI companies, and a small number already have. But the market is young, the public evidence is thin, and most of the price figures you will see online are reports from anonymous sources, not published rate cards. This guide explains what is known, what is guesswork, and what a business owner should check before talking to any buyer.
Here is the short version. AI developers want data that is accurate, specific to real work, and legally clean. Public web text is running low and is increasingly restricted, so private data with clear rights has become more attractive.12 Reported deals range from small payouts for the contents of a failed startup's Slack and email archives to contract values above $200 million for large content owners.345 Whether your own data can sell depends on four things: who owns it, whether personal information can be removed, whether it shows real expert work, and whether the buyer will accept your terms.
Quick answers#
| Question | Short answer | Read more |
|---|---|---|
| Can a normal company sell its data to AI companies or AI labs? | Some can. It depends on ownership, privacy, how much real expert work the records show, and whether a buyer needs that kind of data right now. | The short answer |
| Who buys business data? | AI labs, the data and evaluation companies that supply them, enterprise AI teams, synthetic-data builders and data marketplaces. | Who buys |
| What kinds of data sell? | Records that show real work and its outcome: resolved tickets, decision threads, code with reviews and tests, documented workflows. | What is in demand |
| What does it pay? | There is no public price list. Reported deals run from small payouts to contracts above $200 million; units and terms differ a lot. | How pricing works |
| Is it legal? | Often, if your contracts, privacy notices and the law allow it, and usually only after personal information is removed. | Privacy law |
| What is the biggest blocker? | Rights. Customer contracts, privacy promises, employee data and third-party licenses decide what you can sell. | Who owns your data |
| How does a sale work? | Inventory, trace rights, remove risky parts, de-identify, share a sample under NDA, compare offers, sign with counsel, deliver. | Step by step |
| Exclusive or non-exclusive? | Exclusive usually pays more but stops you selling the same data again. Read the term, field of use and deletion rights. | Deal structures |
Why AI companies want business data#
The public web is a finite resource#
Large language models learn from text. For years the main source was the public web. Epoch AI, a research group that tracks AI trends, estimated the stock of usable public human-written text at roughly 300 trillion tokens. It projected that if training trends continue, that stock could be fully used between 2026 and 2032.1 Epoch's estimate covers public text only, and the authors note that techniques such as synthetic data would be needed to keep progress going.1
At the same time, the open web is closing. The Data Provenance Initiative audited the web domains behind popular training corpora and found that restrictions on AI crawlers and in terms of service rose sharply over a single year. In one widely used corpus, C4, terms-of-service restrictions covered about 45% of the content.2 Free, generic web text is also commodity supply. Common Crawl, a nonprofit, publishes a free archive of more than 300 billion pages collected over 15 years.6 In our reading, anything a model builder can get for free from the public web is not worth much to pay for.
Synthetic data does not fully replace human data#
A natural question is whether AI can simply generate its own training data. Researchers have studied this. A paper in Nature found that training models on model-generated content can cause "model collapse," in which the rarer parts of the original data distribution disappear over successive generations. The authors added that data from genuine human interaction with systems will become more valuable as AI-generated content spreads online.7 Synthetic data is useful in many settings, but this result is one reason developers keep paying for real human and business data.
Quality beats volume#
The other pressure is quality. Several research results show that smaller amounts of carefully chosen data can outperform much larger piles of raw text:
- Microsoft researchers trained a 1.3 billion parameter code model on about 7 billion tokens of filtered and synthetic "textbook quality" data. It reached 50.6% on the HumanEval coding benchmark, and the authors credit data quality.8
- The LIMA paper tuned a 65 billion parameter model on only 1,000 carefully curated prompt and response pairs, and argued that most knowledge comes from pretraining, so a small, high-quality tuning set can be enough.9
- The DataComp-LM project found that model-based filtering of web data was the key to a strong training set, and its filtered 2.6 trillion token set let a 7 billion parameter model reach 64% on the MMLU benchmark with less compute than the previous open-data best.10
None of these papers is about buying data from companies. They matter because they explain what a buyer is looking for: specific, correct, well-organized examples of real work, not volume. A support team's resolved tickets, a lawyer's annotated contracts or an engineering team's reviewed code changes may be small by web standards but dense in the kind of signal a developer cannot get from Common Crawl.
Companies have said they want private data#
AI developers have said so directly. In November 2023, OpenAI announced a "Data Partnerships" program seeking large-scale datasets that are not easily accessible online, including human conversations and long-form writing. According to TechCrunch's report, it offered two tracks: open datasets made public, and private datasets that stay confidential.11
There is also reporting on the demand for expert-created work. TechCrunch reported in 2025 that leading AI labs pay Mercor to hire former bankers, consultants and lawyers to write reports and fill out forms used for training, with contractors earning up to $200 an hour, and framed this as a way to get data that companies would not share directly.12 OpenAI's GDPval benchmark, published in 2025, was built from tasks written by industry professionals averaging 14 years of experience across 44 occupations.13 These are signs that labs value examples of real professional output.
Another area is training environments for AI agents. TechCrunch reported in September 2025 that major labs were seeking reinforcement learning environments, which are simulated workspaces where an agent practices multi-step tasks, and that Anthropic leaders had discussed spending more than $1 billion on them over the next year, according to The Information.14 That figure is second-hand and describes a discussion, not a signed commitment. Epoch AI later described the market from interviews: contracts often run six to seven figures per quarter, and enterprise software workflows are a major growth area.15
What the reported deals show#
Most data licensing news so far involves publishers and online communities, not ordinary businesses. These deals still show the range of structures and prices. All figures below are reported by the sources named, and several rest on anonymous people. Companies rarely confirm terms.
| Deal | Reported figure | What the source says | How firm is it |
|---|---|---|---|
| Reddit and Google | About $60 million per year | Reuters, citing three anonymous sources, reported the deal as Reddit prepared to go public16 | Reported, not confirmed by either company |
| Reddit data licensing, all buyers | $203.0 million total contract value | Reddit's IPO filing disclosed contracts signed in January 2024 with terms of two to three years, with at least $66.4 million expected as 2024 revenue. Buyers were not named5 | Company disclosure, via TechCrunch |
| News Corp and OpenAI | Could exceed $250 million over five years | The Wall Street Journal, which News Corp owns, reported the figure, citing people familiar. Neither company disclosed terms17 | Reported, "could be" |
| Axel Springer and OpenAI | "Tens of millions of euros" per year | The Financial Times reported a one-time payment for archive content and recurring payments for current content, non-exclusive18 | Reported, secondhand |
| Shutterstock | Data, distribution and services segment: $137.3 million (2023) and $175.3 million (2024) | The 10-K says demand for its metadata for AI training increased. The filing does not break out AI licensing alone1920 | Company filing, but the segment is broader than AI data |
| Photobucket | About 5 cents to $1 per photo, over $1 per video | Reuters reported these as prices under discussion for roughly 13 billion images and videos, not signed deals21 | Negotiating range |
| Wiley | About $44 million expected from AI deals | infoDOCKET reported the projection and that authors cannot opt out22 | Projection, secondhand |
| Stack Overflow and OpenAI | No figure | Stack Overflow announced an API partnership in May 2024 with attribution of community content23 | Primary source, terms not disclosed |
A few lessons come out of the table. First, headline numbers mix very different things: annual payments, total contract value, revenue segments and projections. Second, the large figures belong to companies with huge, unique archives. Third, the per-unit prices in the Photobucket and Defined.ai reporting are a useful reminder that generic data sells at low unit prices, and that volume alone does not make a business dataset valuable.21
Smaller and stranger sales#
At the other end are sales by failing companies. Forbes reported in April 2026 that SimpleClosure, a company that helps businesses shut down, launched a service for startups to sell their code and workspace data, such as Slack messages, emails and Jira tickets, and said it had processed about 100 deals in a year with payouts ranging from $10,000 to $100,000.3 In October 2026, MIT Technology Review reported that the service had handled more than 150 deals, that code or data sales were part of 47% of SimpleClosure's deals, and that buyers included foundation model labs, vendors building simulated workspaces and tech companies building models.4
The same report said Google outbid Mercor for Spirit Airlines' data in August 2026 for $10 million, a figure we could find in only that one outlet, and described privacy objections, including opposition from the airline's flight attendants' union and a lawyer calling such data "legally radioactive."4 We return to this in the section on bankruptcy sales.
The legal backdrop#
Buyers care about clean rights because the legal risk is real. In September 2025 Anthropic agreed to pay $1.5 billion to settle a lawsuit by book authors, reported as about $3,000 per book across roughly 500,000 books.24 That case concerned books obtained from pirate sources, not licensed business data, but it shows why serious buyers now ask where data came from and who agreed to its use.
What kinds of business data are in demand#
No public price list exists for business data by type, so this section rests on what is publicly known about how models are trained and evaluated. Where we are offering our own judgment, we say so.
| Data type | Why a buyer might want it | Main rights and privacy issue | Evidence |
|---|---|---|---|
| Customer support conversations | Real problems, real resolutions, and the tone of a working support team | Customer personal data, call recording consent, customer contract limits | Support-style dialogue is a recognized tuning data type, but a free synthetic dataset also exists, which limits the price of generic examples25 |
| Code with reviews and fixes | Pairs of problem and solution used to train and test coding agents | Open-source license terms, secrets in code, employee authorship | SWE-bench builds tasks from real issues and the pull requests that fixed them26; code models are trained on permissively licensed code with opt-outs27 |
| Expert documents, SOPs and workflows | Examples of professional work product and multi-step procedures | Confidential client material, trade secrets | GDPval tasks come from professionals' real work13; labs pay for expert-written reports12 |
| Workplace messages and tickets | Material for simulated workspaces and agent training | Employee privacy, customer data in messages | Reported in failed-company sales4; Epoch reports high-fidelity replicas of products such as Slack costing about $300,00015 |
| Healthcare records and imaging | Clinical detail that is hard to obtain | HIPAA de-identification, state health privacy laws | Protege says it licenses de-identified data, with a focus on healthcare28; Stanford AIMI publishes a commercial license price for clinical datasets29 |
| CRM history and marketing data | Judgment: sales and campaign outcomes are structured and tied to results | Personal data of leads and customers | We found no public reporting of buyers for these types |
Customer support conversations#
Support conversations pair a customer's problem with a resolution written by a trained employee. That is useful for teaching a model how a problem is described and how a good answer is phrased. The caution is price. A published dataset from Bitext offers about 26,872 support question and answer pairs across 27 intents, built in a hybrid synthetic way and released under a sharing license.25 Generic support examples can be produced cheaply. What a real company has that a synthetic set does not is the messy, domain-specific detail of its own product, and that is the part a buyer would value. This is our inference, not a price signal from the market.
Code with reviews and commit history#
Code is the best documented case. The Stack, a large code dataset from the BigCode project, collects permissively licensed source code in 30 languages and offers developers a way to check whether their code is included and to request removal.27 SWE-bench, a benchmark for coding agents, was built from 2,294 real software problems, each pairing a GitHub issue with the pull request that fixed it.26 The practical meaning for a software company is that the history of how problems were found, discussed and fixed has structure a model can learn from. The licensing meaning is that the license on every dependency and every contribution matters.
Expert documents, SOPs and workflows#
A standard operating procedure, a legal template library or a set of annotated reports captures how professionals do their jobs. GDPval and the Mercor reporting above show that expert-produced work is the kind of data labs value.1312 The risk is confidentiality: much of this material belongs partly to clients and is covered by non-disclosure agreements.
Healthcare data#
Healthcare is the most regulated category and also the one with the clearest published prices. Protege, a data licensing platform, describes itself as curating and de-identifying data from many providers and licensing it to AI developers, with a focus on healthcare, media and video.28 Stanford's AIMI center publishes a commercial license price of $70,000 per dataset per year for its de-identified clinical datasets, the rate for agreements through August 2025.29 That is one academic seller's price, not a market rate. We cover HIPAA's two de-identification methods later in this guide.
Who buys: AI labs, data vendors and marketplaces#
"Selling data to AI labs" usually means selling to one of six kinds of buyer. Only some deal with an ordinary company directly; many reach AI labs through the companies in between. This summary reflects how we see these buyers work in practice; requirements change, so confirm them with each buyer.
| Buyer | What they want | How deals work | How they take intake |
|---|---|---|---|
| AI labs | Large, well documented sets with clear rights and several years of history | A negotiated license; no standard price, terms set deal by deal | Expect a prepared package: what the data is, where it came from and what you can license |
| Expert-data and labeling vendors | Records that show a skilled person doing a task from start to finish, with a verifiable result | Quote-based; structure varies by vendor and dataset | A short description first, then a sample under NDA |
| Data marketplaces and licensing platforms | Packaged datasets in a standard format, with a clear license and documentation | Often a listing arrangement or a share of each sale | Self-serve listing is common; you do the packaging |
| Enterprise AI teams | Domain-specific records from their own field, with the context that makes them usable | A license set by the buyer and the dataset, often one named buyer | A small number of conversations with a named contact |
| Synthetic-data builders | Clear structure, a range of edge cases and data free of personal information | Quote-based, often smaller samples than a full archive | They start from a small, well described sample |
| Evaluation and benchmark builders | Records with a verifiable outcome: a passing test, a confirmed fix, a completed order | Quote-based; usually smaller, higher-quality sets | Specific record types and a sample before anything else |
For most companies the practical route to an AI lab runs through the data and evaluation companies that supply them, a marketplace, or a broker that knows which buyer needs what this quarter. Our buyer guide goes deeper on each type.
What does not sell#
Not every dataset has a buyer. Some of this is judgment, and we mark it as such.
- Data you do not have the right to sell. This is the most common reason. Customer contracts, privacy promises, employee relationships and open-source licenses can each block a sale. The rights section below covers how to check.
- Generic public data. Public web text is plentiful and free, as Common Crawl shows.6 A copy of your public website is unlikely to be worth paying for. This is our reading of the evidence.
- Raw, messy, undocumented exports. The Data Provenance Initiative and the Datasheets for Datasets proposal both argue that datasets should come with documentation of where they came from, how they were collected and what they are for.230 In our view a buyer's lawyers will ask for exactly that. Data with no provenance record is harder to price and harder to buy.
- Data that cannot be de-identified. If personal details are woven through the content and cannot be removed without destroying its value, buyers are likely to pass. Free-text clinical notes are a typical example. This is our judgment.
- Synthetic or model-generated content. The model collapse research is the reason buyers do not want training data that was mostly generated by other models.7
- Tiny or one-off datasets. Expert-data contracts reported by Epoch involve per-task prices of $200 to $2,000 and require calibrated difficulty and reliable graders, so a handful of examples without structure is not a product.15
Who owns your data, and what you can actually license#
Holding a database is not the same as holding the right to sell it. Before a buyer sees anything, a rights review should answer one question: for each source of data, what permission do we have, from whom, and does it cover this use?
Ownership is mostly set by contract#
Vorys, a US law firm, notes that ownership of data between parties is mostly set by contract, because raw facts are generally not protected by copyright. It advises spelling out permitted uses rather than relying on the word "own."31 Morgan Lewis makes a related point from the vendor side: what matters is the rights a party holds to use, retain and benefit from data, and broad training rights can let learnings stay in a model indefinitely, so agreements should deal explicitly with aggregated and anonymized data.32 Both are general commentary, not rules. They point to the same practical step: read the contracts that govern where your data came from.
Customer contracts and privacy promises#
If your data came from customers, your agreements with them and your public privacy policy set the limits. Three sources of risk are worth checking:
- Confidentiality clauses. Many enterprise contracts bar using customer content for anything beyond providing the service.
- Promises about AI training. The US Federal Trade Commission has said that companies must keep their privacy and confidentiality promises wherever they were made, that there is "no AI exemption" from existing law, and that a promise not to use customer data for training is enforceable, including against indirect workarounds.33
- Quiet changes to terms. FTC staff have written that it may be unfair or deceptive to loosen data-use terms, for example to allow AI training, and notify customers only through a quiet retroactive change to a terms of service or privacy policy.34
The FTC has also said it has required companies that unlawfully obtained data to delete the models and algorithms built from it.33 Examples include the Everalbum settlement over photos and videos, the proposed Rite Aid order over facial recognition images, and the WW International and Kurbo order over children's data.353637 For a data seller, the lesson is concrete: if a buyer trains a model on data you had no right to sell, the consequences can reach the model itself, and a careful buyer will demand warranties that you cannot give if you have not done the review.
Employee data#
Workplace messages, tickets and call logs contain employees' personal information as well as customers'. Guidance from European regulators, summarized by Irish law firm A&L Goodbody, says employee consent is generally not a workable basis for processing because of the imbalance of power, and that employers relying on legitimate interests must show necessity and proportionality.38 UK guidance on monitoring workers, summarized by Freeths, calls for a defined purpose, the least intrusive means and clear notice to workers, and the regulator's own page notes that its guidance is under review.39 In California, the Berkeley Labor Center notes that privacy law now covers employees, contractors and applicants as well as consumers, because the workforce exemption expired on January 1, 2023.40
Call recordings and chat transcripts#
Support calls raise a separate issue. California Penal Code section 632 bars recording a confidential communication without the consent of all parties.41 Recent litigation targets the way AI vendors use recorded calls. In a February 2025 ruling in Ambriz v. Google, a federal court let wiretap claims proceed over a contact center AI product, applying a test under which a vendor can count as a third party if it has the capability to use call data for its own purposes.42 In August 2025, a court allowed similar claims to proceed against an AI phone-ordering vendor in Taylor v. ConverseNow, reasoning that the vendor allegedly used call data to improve its own product.43 These are rulings at the pleading stage, so they do not decide who wins, but they show why a company should know what its callers were told before licensing recordings.
Trade secrets#
Documents, SOPs and workflows may contain trade secrets. Under US federal law, business information qualifies as a trade secret only if its owner takes reasonable measures to keep it secret and it has independent economic value because it is not generally known.44 Sharing it with a buyer therefore needs a non-disclosure agreement, and law firms disagree on the details. Holland & Knight cautions that a time-limited NDA can jeopardize trade secret protection and recommends open-ended confidentiality for trade secrets.45 A 2026 federal decision reported by Faegre Drinker held that unauthorized disclosure by a recipient is still misappropriation even where an NDA exists.46 Treat these as signs that the paperwork around a sale needs a lawyer, not as settled rules.
Code and open-source licenses#
Software companies often assume that all their code is theirs to license. In practice most codebases include open-source components. The GNU project's FAQ says the GPL does not require you to release modified versions kept private inside a company, but if you release a modified version publicly you must make its source available under the GPL.47 The AGPL goes further: its section 13 requires offering source to users who interact with a modified version over a network.48 The MIT license requires that copyright and permission notices stay with copies.49 We did not find a source that settles whether these licenses apply to AI training use, so the right approach is to separate code you wrote and own from third-party code, and to ask counsel about the rest.
Copyright and the licensing market#
In a May 2025 pre-publication report, the US Copyright Office said voluntary licensing for AI training is already happening in some sectors and appears likely in others, and that where licensing is available or feasible, that weighs against a fair use finding. The report is not binding law and the Office said a final version would follow.50 The practical effect is that buyers have a reason to prefer licensed data to scraped data, and sellers have a reason to document what they are licensing.
Privacy law, in plain terms#
The privacy rules that apply to you depend on whose data is in the set and where they live. This is a map, not a legal opinion.
GDPR and other European rules#
The EU's General Data Protection Regulation defines personal data as information relating to an identified or identifiable person, directly or indirectly, for example through a name, an identification number, location data or an online identifier.51 Data that has been pseudonymized, meaning it can no longer be tied to a person without extra information held separately, is still personal data. Only truly anonymous data falls outside the regulation, and anonymity is judged by all the means reasonably likely to be used to identify someone, weighing cost, time and available technology.52 The UK regulator says the same about pseudonymized data and adds that if you share it without the key, the recipient may hold anonymous information.53 The European Data Protection Board adopted guidelines on pseudonymization in January 2025, and a law-firm summary notes that they give no clear test for when pseudonymization is effective.54
Two further principles matter for a data sale. The first is purpose limitation: personal data must be collected for specified purposes and not further processed in a way that is incompatible with them, and the regulation lists factors for judging compatibility, including the link between the purposes, the context of collection and the consequences for people.5556 The second is the need for a lawful basis, and the regulation lists six, including consent and legitimate interests. Legitimate interests fail if overridden by the person's rights and freedoms.56
In December 2024 the EDPB issued an opinion on AI models and personal data. It said a model trained on personal data is not automatically anonymous, and that anonymity requires that the likelihood of extracting personal data from the model, directly or through queries, is insignificant, assessed case by case.57 It also described what happens when a model was built using unlawfully processed personal data, saying the effect on later use depends on the facts, including whether a different organization later deploys the model and whether the model has been anonymized.57 For a seller, the takeaway is that a European buyer may ask for proof that your data was lawfully obtained.
When your own company handles personal data for a customer under a data processing agreement, GDPR Article 28 says a processor may act only on the controller's documented instructions, and a processor that decides purposes and means itself is treated as a controller for that processing.58 That is our reading of how the article would apply to a data sale, not a statement from a regulator: a vendor that sells its customers' data for its own gain may be taking on more than it realizes.
California and other US states#
The California Consumer Privacy Act defines "sell" broadly as disclosing or making personal information available to a third party for money or other valuable consideration, with exceptions that include some asset transfers in a merger or bankruptcy.59 Consumers can opt out of sale or sharing, including through a browser signal, and the law applies to businesses over certain revenue or consumer-count thresholds.60 The law also defines "deidentified" information. Data counts as deidentified only if it cannot reasonably be used to infer information about or be linked to a consumer, and the business takes reasonable measures against re-association, publicly commits not to reidentify it, and binds recipients by contract to the same terms.59 That last step matters for a seller: your contract with a buyer is part of what makes data "deidentified" in California.
California is not alone. The International Association of Privacy Professionals counted 19 US states with comprehensive privacy laws as of its October 2025 update, and said they commonly give consumers the right to opt out of the sale of personal data.61 The count has probably grown since then, so check a current tracker.
De-identification: methods and limits#
De-identification means changing data so that it no longer points to a person. It is the most important technical step in preparing business data for sale, and also the one most often oversold.
HIPAA's two methods#
For health data covered by the US Health Insurance Portability and Accountability Act, the regulation recognizes two routes to de-identification. We rely here on the federal regulation text, 45 CFR 164.514(b).62
| Safe Harbor | Expert Determination | |
|---|---|---|
| What it requires | Removal of 18 types of identifiers, plus no actual knowledge that what remains could identify someone | A qualified expert concludes that the risk of identifying anyone, alone or combined with other reasonably available information, is very small |
| Examples of what must go | Names, geography smaller than a state (with a limited exception for three-digit ZIP codes), all date elements except year, ages over 89, contact details, record and account numbers, device identifiers, URLs, IP addresses, biometrics, full-face photographs | Depends on the data and the expert's analysis |
| Documentation | The identifiers are removed and the entity lacks actual knowledge | The expert documents the methods and results of the analysis |
| Best suited to | Structured data where the identifiers are easy to find | Rich data such as free text, images or detailed records, where simple removal does not reduce risk enough |
The identifier list covers relatives, employers and household members of the individual as well as the person.62 This table is a summary of regulation text for orientation. Whether a particular dataset meets either standard is a question for a privacy professional.
Removing identifiers is not the same as removing risk#
History offers repeated warnings that "anonymous" data is often not:
- Latanya Sweeney of Harvard found that about 87% of the US population, 216 million of 248 million people, had a unique combination of five-digit ZIP code, gender and date of birth, using 1990 census data. This is an estimate of uniqueness, not of how many people were actually identified.63
- Narayanan and Shmatikov showed in 2006 that anonymous movie ratings from roughly 500,000 Netflix subscribers could be matched to named people with a little background knowledge, using IMDb as the outside source.64
- AOL released about 20 million search queries from more than 650,000 users in August 2006. The New York Times identified one user within days, and AOL's chief technology officer resigned.65
- A 2019 study in Nature Communications estimated that 99.98% of Americans could be correctly re-identified in any dataset using 15 demographic attributes. The figure comes from a statistical model, not from re-identifying a real dataset.66
The lesson for text data is the same as for tables: people are identified by combinations of details, not just names. A support transcript can reveal a person through a rare job title, a street, an order number and a date.
Methods that exist#
- Redaction tools. Microsoft's Presidio, now hosted by the Data Privacy Stack project, is an open-source toolkit that detects and anonymizes personal data in text and images using entity recognition, patterns and rules. Its documentation says there is no guarantee that it finds all sensitive information, so extra safeguards are advised.67
- k-anonymity. A dataset is k-anonymous if each person's record cannot be distinguished from at least k minus 1 others. Sweeney introduced the idea in 2002.68
- Government guidance. NIST Special Publication 800-188, finalized in 2023, covers de-identifying government datasets, including removing identifiers, transforming quasi-identifiers and using controlled-access sharing such as enclaves. It warns that tools that merely mask personal data may not be enough.69 It is written for federal agencies, so it is a benchmark and not a legal requirement for private sellers.
- Differential privacy. A mathematical approach that adds calibrated noise. NIST published guidelines in 2025 for evaluating claims of differential privacy.70 It fits statistics better than free text.
- Pseudonymization. Replacing names with codes. As noted above, regulators treat it as still personal data while anyone holds the means to re-link it.53
- Controlled access. Instead of handing over files, the seller lets a buyer train inside an environment it controls, so data never leaves. NIST's guidance describes sharing models of this kind.69
Why model memorization matters#
A buyer's model can sometimes repeat what it learned. Researchers extracted hundreds of verbatim sequences from GPT-2's training data in 2021, including personal information, chat logs and code.71 A 2023 paper by researchers including Nicholas Carlini extracted gigabytes of training data from open and closed models, including ChatGPT, using a "divergence attack," and concluded that alignment does not eliminate memorization.72 These attacks target models that have already been trained. They are the reason personal and confidential details should be removed before sale, not after.
How pricing works#
There is no standard price list for business data. What exists is a mix of valuation theory, a few published unit prices, and reported deal sizes.
Three ways to value data#
Deloitte describes three approaches used to value data assets. The income approach discounts the future benefits the data produces. The cost approach estimates what it would cost to recreate or replace the data. The market approach uses prices from comparable transactions. Deloitte notes that reliable comparable transactions are scarce, so the market approach works best as a reasonableness check, and that methods are usually combined.73
For a seller, this means two things. A buyer is likely to think in terms of what the data replaces: the cost of paying experts to produce similar examples, or the benefit a model gains. And because comparables are few, the first offer you see may say more about the buyer's budget than your data's worth.
Reported price points#
The table below collects published or reported figures. Each has a different unit and a different context, and none is a quote for your data.
| Item | Reported figure | Source type and caveat |
|---|---|---|
| Generic text | About $0.001 per word | Defined.ai figure reported by Reuters via The Decoder in April 2024; dated21 |
| Images and short video | $1 to $2 per image, $2 to $4 per short video | Same report21 |
| Long video | $100 to $300 per hour | Same report21 |
| Creator video footage | $1 to $4 per minute | Reported by Bloomberg, via The Decoder, January 2025; video only74 |
| Call center audio | $5 to $25 per hour off the shelf, $50 to $300 per hour custom | A vendor's own blog, with no cited source for the prices75 |
| De-identified clinical dataset | $70,000 per dataset per year | Stanford AIMI's published rate for agreements through August 2025; one academic seller29 |
| Failed-company workspace data | $10,000 to $100,000 per deal | Forbes via Gizmodo, April 20263 |
| Expert-written AI tasks | Typically $200 to $2,000 per task | Epoch AI, from interviews15 |
| High-fidelity software replica | About $300,000 for a complex product such as Slack | Epoch AI, from interviews15 |
| Exclusivity premium | Exclusive deals roughly 4 to 5 times non-exclusive | Epoch AI, for environments, from interviews15 |
Analyst reports estimate the overall market for AI training datasets in the billions of dollars. One reseller summary of a Grand View Research report lists about $3.2 billion in 2025 growing to about $16.3 billion by 2033.76 We do not recommend relying on these estimates. They are definitions-dependent forecasts from firms that sell reports, and estimates from different firms vary.
What tends to move a price#
Public evidence supports some of the following and the rest is our judgment, marked as such.
- Exclusivity. Epoch's interviews suggest exclusivity commands a premium of several times, in the environments market.15
- Quality and structure. Buyers of environments value reliable grading and calibrated difficulty.15 More broadly, the quality research above explains why curated data is worth more than raw volume.9 (Our judgment applies this to business data.)
- Rights clarity. Clean provenance and clear rights reduce a buyer's legal risk. (Our judgment, supported by the legal cases above.)
- Uniqueness. Data a developer cannot get elsewhere is worth more. (Our judgment.)
- Preparation cost. De-identification, cleaning and documentation cost money, and someone pays. Ask who.
- Alternatives. Free synthetic datasets, such as the Bitext set, put a ceiling on generic examples.25
Deal structures#
Once a buyer is interested, the term sheet and contract decide what you are actually selling. Law firm commentary on AI data licensing agrees on a handful of points. Some of the sources below are written from the buyer's side, such as Sidley's, or for companies licensing technology from a vendor, such as Best Lawyers', so sellers should read them with that in mind.
| Term | What to decide | What public sources say |
|---|---|---|
| Exclusivity | Can you license the same data to others? | Axel Springer's reported deal is non-exclusive18. A Malaysian law firm advises settling exclusivity up front and, for sellers, keeping the right to license to others77. Epoch reports an exclusivity premium15 |
| Term | How long does access last? | Reddit's disclosed contracts ran two to three years5. One practitioner memo suggests model rights could be perpetual while dataset access is a finite license78 |
| Field of use | What may the buyer do with it? | Law-firm commentary recommends limiting the license to named models or model families, and saying whether fine-tuned or successor versions are covered7978 |
| Derived models and datasets | Who owns outputs, curated subsets and annotations? | Sidley says ownership of derived datasets and model outputs should be assigned expressly, because the treatment of models as derivatives is unsettled79 |
| Fee model | Flat fee, annual fee, usage-based, or revenue share? | One firm says a fixed annual fee based on dataset size and quality is typical77. Reddit's disclosures describe contract value, not a royalty5. We found no public source on revenue-share rates in AI data deals |
| Deletion and audit | What happens at the end? Can you check compliance? | Sidley says deletion and audit duties may survive termination and should be negotiated up front79. Best Lawyers suggests covering backups and caches and sample certification of deletion80 |
| Warranties and indemnity | What do you promise about rights? | Sidley calls provider warranties of rights and non-infringement, and indemnity for third-party claims, increasingly standard79 |
| Unwinding | Can data be removed from a trained model? | The Malaysian firm warns that removing data from a trained model may be infeasible or need costly retraining, so sellers may have to accept it stays77 |
Exclusive or non-exclusive#
Exclusive deals pay more but cap your future income from the same data and may limit your own use. A non-exclusive license lets you sell to several buyers but gives each less reason to pay a premium. For data that only you can produce, such as recurring business activity, a non-exclusive or time-limited exclusive license can fit. Seek advice before agreeing to exclusivity for a long term.
Flat fee or revenue share#
A flat fee gives certainty. A revenue share ties your payout to the buyer's success but depends on a buyer you cannot audit easily. Public sources describing actual AI data deals say little about revenue shares, so expect to negotiate this from first principles. Created by Humans, a licensing marketplace for authors, takes a cut of each deal but TechCrunch reported no percentage and we found none published.81
What a seller should insist on#
From the sources above and standard practice, a seller will usually want a field-of-use limit, a prohibition on re-identification, deletion and audit rights, a confidentiality clause, clear ownership of the original data, and a cap on liability. These are not legal advice. A lawyer who has done data licensing should review the deal.
The process, step by step#
Whether you work with a broker or sell directly, the sequence is similar. These steps are our recommended order, based on the sources above and common practice, not a legal requirement.
- Inventory what you have. List each source of data: systems, date ranges, volume, formats and who created it. Include what is in third-party tools such as support platforms and chat apps, and note where personal data appears.
- Trace the rights. For each source, find the contract, policy or consent that governs it. Mark what you own outright, what customers own, what employees or contractors created, and what is third-party or open-source. The readiness checklist later in this guide covers the same ground.
- Remove or restrict the risky parts. Decide what to exclude entirely, for example data covered by confidentiality clauses or customers who never agreed. Anything left in needs a plan for personal data.
- De-identify and document. Apply the technique that fits each data type, test the result, and write down how it was done and by whom. A buyer will ask for this record, much as the Datasheets for Datasets proposal argues every dataset should ship with documentation of its origins, composition and intended use.30
- Package a sample. Prepare a small, representative, de-identified sample and a short description. A sample lets buyers judge quality without seeing everything. Share nothing outside a signed confidentiality agreement.
- Find and screen buyers. Build a list of possible buyers, check their data-use and security practices (see the next section), and approach them under non-disclosure terms.
- Get offers and compare them. Compare more than price: exclusivity, term, field of use, deletion rights, indemnity and the buyer's ability to protect your data.
- Negotiate and sign with counsel. Have a lawyer who has done data licensing review the agreement, the warranties and the indemnity.
- Deliver and monitor. Transfer through a secure method, keep a record of what was delivered, and calendar the deletion and audit dates.
How to evaluate a buyer#
Selling your data means trusting the buyer with it. A buyer is not just a source of payment. Some questions to ask, and what public sources say about each area:
What will the buyer do with the data?#
Licensing data for training is different from using an AI tool. Major AI providers say that data sent through their business products is not used for training by default: Anthropic says it does not use inputs or outputs from its commercial products, including its API, for model training by default;82 OpenAI's API documentation says data sent to the API is not used to train its models unless the customer opts in;83 and Google's Vertex AI documentation says Google will not use customer data to train or fine-tune models without prior permission.84 These policies concern using the tools. They are not terms of a data sale, where training is the point. Do not confuse the two when a buyer says they "do not train on customer data."
Can the buyer protect it?#
Ask for the buyer's security evidence and how data is stored, accessed and deleted. The AICPA's SOC reports are one form of independent assurance about a service organization's controls.85 NIST's AI Risk Management Framework, released in January 2023 with a generative AI profile in July 2024, is voluntary guidance that a buyer can use to show how it manages risks.86 Whether a buyer holds these is our suggested test, not a rule, and no certificate guarantees safe handling.
Real incidents show why it matters. Security Affairs reported in April 2023 that Samsung employees pasted chip source code and meeting notes into ChatGPT on three occasions in under a month, and that Samsung warned staff the data could not be retrieved.87 That was about employees using a tool, not licensing, but it illustrates how confidential material can leave a company's control.
Will the buyer expect documentation?#
Probably. The Data & Trust Alliance published Data Provenance Standards in July 2024 with 22 metadata fields in three groups covering source, provenance and use, including consent documentation, license to use and confidentiality classification. The standards are voluntary, but they are the closest thing to a buyer-side diligence checklist we found.88 Preparing this information early speeds a deal.
What is the buyer's track record?#
Ask for references and what the buyer has disclosed publicly. Look at its public statements about data practices, and at news. Companies that changed terms to allow AI training without clear notice have faced strong reactions, as the next section shows. Be careful of any buyer that wants broad rights, perpetual access and no deletion.
Risks to weigh#
Reputation#
Customers react badly when they feel their data was used without notice. In August 2023, a blog reported that Zoom's terms seemed to allow AI training on "service generated data." Zoom clarified a day later and amended its terms to say it would not train AI models on audio, video or chat content without consent, though privacy advocates remained skeptical.89 In May 2024, Slack's privacy principles said it analyzed customer data to develop AI and machine learning models, with opt-out available only by emailing the company. Slack said it had not trained generative or third-party language models on customer data and that its wording was unclear.9091 In June 2024, Adobe's updated terms drew a backlash over fears of AI training on customer content, and Adobe said it did not train generative AI on customer content.92 In all three cases the companies said practice had not changed and the wording was the problem, so we do not state that any of them did train on customer content. The reputational damage came from the wording alone.
Automattic, which owns Tumblr and WordPress.com, was reported by 404 Media in February 2024 to be preparing to share content with OpenAI and Midjourney, and an alleged internal post said the first batch wrongly included private posts and deleted blogs. Automattic said it would share only public content from sites that had not opted out.93 The lesson is operational: errors in selecting data are the sort of thing that become news.
Re-identification#
Even careful de-identification can fail, as the history in the de-identification section shows. A seller should require the buyer to commit not to re-identify and to report any suspected breach. In California, that commitment is part of the legal definition of deidentified data.59
Competitive leakage#
If you sell data that reflects how you serve customers, your competitors may eventually use models trained on it. This is a real tradeoff and a reason to negotiate field-of-use limits, exclusivity terms or a restriction on selling to named competitors. The research on memorization shows models can repeat their training data in some conditions, so material that gives away pricing, strategy or customer lists should be excluded before sale rather than relied on to stay hidden.7172 We found no public case of a company's trade secrets leaking from a model it sold data to, so this is a risk by reasoning, not an observed event.
Legal exposure after the sale#
The FTC has required deletion of models and algorithms built from unlawfully obtained data in several cases.33 If a buyer trains on data you had no right to sell, the buyer may face this. In contracts, that risk flows back to you through warranties and indemnity.79 The best protection is the rights review done before anyone signs.
Selling data in a bankruptcy or wind-down#
Companies that are closing sometimes sell their data as an asset. This is a real part of the market, and it carries unique rules.
In the United States, section 363(b)(1) of the Bankruptcy Code says that if a debtor's privacy policy promised not to share personal information with unaffiliated third parties, the trustee may sell or lease it only consistently with that policy, unless a consumer privacy ombudsman is appointed and the court approves.94 Section 332 requires the US Trustee to appoint an impartial ombudsman at least a week before the sale hearing, who reports to the court on the privacy policy, the privacy effects and alternatives.95 In March 2025 the FTC's chair wrote to the trustee in the 23andMe bankruptcy that its privacy promises must be honored in any sale. A law firm's summary says the FTC cited section 363(b)(1) and urged that buyers expressly agree to follow the privacy policies.9697
The California privacy law, for its part, excludes from the definition of sale certain transfers as part of a merger or bankruptcy, provided the data is used consistently with the law.59
Not every wind-down is a bankruptcy. SimpleClosure's service, as reported, helps shuttered startups sell code and workspace data and strips personal information first, while a privacy advocate cited by Gizmodo called employee privacy a key concern.3 MIT Technology Review's report included a union's objection to the Spirit Airlines sale and a lawyer's comment that such data can be "legally radioactive."4 It also noted that there is no federal law banning such sales.4
Brokers or selling direct#
Some companies sell directly to AI developers. Others use an intermediary. Both work, and the right choice depends on what you have.
What intermediaries exist#
A small set of platforms publicly describe themselves as intermediaries for AI training data:
- Protege describes itself as aggregating data from many providers, curating and de-identifying it, and licensing it to AI developers, with a focus on healthcare, media and video.28
- Troveo licenses video, audio and business data to AI developers and lists no prices on its site, only a request for an estimate.98
- Created by Humans lets authors license rights to AI developers and takes a cut of each deal; the percentage is not public.81
- Cloud data marketplaces such as Snowflake Marketplace and AWS Data Exchange let providers list datasets, but neither page we reviewed states provider fees.99100
- Extruct's June 2026 directory tracks 15 companies in this category, split into those that collect and license data, rights and IP brokers, and creator marketplaces.101
Fees and revenue splits are almost never public. Ask any intermediary exactly how it is paid before you sign.
Selling direct#
Direct sales can save the intermediary's cut and give you full control. They require that you can find the right buyer teams, run rights and de-identification work, and negotiate with counterparties that have more legal resources. Large content owners such as publishers and online communities have done direct deals.1617
Using a broker#
A broker takes on some of the work: finding buyers, running the rights and privacy review, preparing the data, and negotiating. A broker also has a conflict of interest, because most brokers are paid when a deal closes. Our How it works page says SellYourAIData takes a commission only if a deal completes, so our incentive is to see deals made. The questions to ask any broker, us included, are below.
- How are you paid, and what percentage?
- Who owns the buyer relationship and the right to re-sell the data?
- What rights and privacy review do you do, and who signs off?
- How do you de-identify, and what happens if re-identification is found?
- Do you work with a lawyer I choose?
- Can I see your agreement before I send data?
- What exclusivity do you require from me?
Readiness checklist#
Use this list before you contact any buyer or broker. A "no" is not the end, but it shows what to fix first.
- We have a written inventory of data sources, dates and volumes.
- We know which contracts and policies govern each source.
- Our customer contracts allow, or we have obtained permission for, this use of the data.
- Our privacy policy does not promise anything inconsistent with a sale.
- We know whether the data includes employee or contractor personal information, and what employees were told.
- If we recorded calls, we know what callers were told and which laws apply.
- Code in scope is ours, and third-party and open-source components are identified.
- We can remove personal and confidential information, and we can test and document the result.
- The data shows real expert work: decisions, resolutions, reviews or procedures.
- Someone inside the company has authority to approve a sale and sign confidentiality terms.
- We have a lawyer who can review a data license.
- We have decided what we will not sell, such as strategy, pricing or customer lists.
Glossary#
Anonymization. Changing data so people cannot be identified by any means reasonably likely to be used. Stricter than pseudonymization.52
De-identification. Removing or altering identifying details. In HIPAA, it means meeting either Safe Harbor or Expert Determination.62
Differential privacy. A mathematical technique that adds noise so that results reveal little about any one individual.70
Expert Determination. A HIPAA route in which a qualified expert documents that re-identification risk is very small.62
Field of use. The limit on what a buyer may do with licensed data, such as training a named model for a named purpose.
Fine-tuning. Further training of an existing model on a smaller, specific dataset. The LIMA paper tuned a large model on 1,000 curated examples.9
Model collapse. The degradation seen when models are trained on model-generated data over successive generations.7
Provenance. The documented origin and handling history of a dataset.88
Pseudonymization. Replacing identifiers with codes while keeping a way to reverse the change. Still personal data under GDPR.52
Reinforcement learning environment. A simulated workspace where an AI agent practices tasks and receives feedback.14
Safe Harbor. The HIPAA method of removing 18 listed identifier types, with no actual knowledge that the remainder can identify someone.62
Training data. Examples a model learns from, as distinct from data it is asked to process at use time.
What changed in this edition#
We update this guide every month. Changes in each edition:
November 2026
- Retitled as the complete guide to selling your data to AI companies and AI labs, with the month in the title so readers can see it is current.
- Added a quick-answers table at the top and a who-buys table comparing AI labs, data vendors, marketplaces, enterprise AI teams, synthetic-data builders and evaluation builders.
- Added our own observation of current deal ranges in the pricing section, labelled as first-party.
- Added an FAQ on selling directly to an AI lab, and an author byline with credentials.
Where to go next#
If you are still deciding whether your data is a candidate, the quickest step is to list your sources and the contracts behind them. Our free valuation asks for a short profile with no files or raw data and replies with a first view on fit, and you can read how the process works on How it works. For specific data types, see customer service data, code, documents and SOPs and healthcare. If you want to read about named companies in the market, our comparisons cover several vendors with the same source-cited approach.
Frequently asked questions
Some can, but it is not guaranteed. Reported sales so far involve publishers, online communities and failed startups, plus expert-written data. Whether yours sells depends on ownership, whether personal information can be removed, and whether it shows real work. See what kinds of business data are in demand.
There is no standard price list. Public figures are reports with different units and contexts, from cents per photo to six-figure annual fees. A buyer will usually think about what it would cost to produce similar examples. Be cautious of anyone who quotes a value before looking at your data and your rights. See how pricing works.
Often only if your contracts, privacy notices and applicable law allow it, and usually only after personal information is removed. Rules differ by country and state. This guide is general information, not legal advice. Ask a lawyer before you share anything.
It means removing or altering details that point to a person. For health data covered by HIPAA there are two defined routes, Safe Harbor and Expert Determination. For other data there is no single standard. It lowers risk but does not eliminate it, so contracts should also bar buyers from re-identifying people. See de-identification.
An exclusive license stops you from licensing the same data to others, so buyers usually pay more for it. A non-exclusive license lets you sell to several buyers. Epoch AI reported that exclusive deals for AI environments cost roughly four to five times as much as non-exclusive ones. See deal structures.
Sometimes. The large lab deals in the public record are with big content owners such as publishers and online communities. Most companies reach AI labs through the data and evaluation companies that supply them, through marketplaces, or through a broker. The who buys table compares each route.
Both are possible. Large content owners have done direct deals. A broker can help find buyers and prepare the data, but is usually paid when a deal closes, so ask how it is paid and what it does about rights and privacy. We are a broker, which is why this guide lists questions to ask any broker, including us. See brokers or selling direct.
Sometimes. Failed startups have sold code and workspace data, according to press reports. In a US bankruptcy there are privacy rules for selling personal information, and privacy promises must generally be respected. See selling data in a bankruptcy or wind-down.
List your data sources, find the contracts and policies that govern each, and note where personal information appears. Then talk to counsel and to a buyer or broker under a confidentiality agreement. The readiness checklist covers the questions to answer first.
Sources
Every numbered reference above points to an entry here. Figures come from these pages as of the date shown at the top of the article. Where a source reports a number it got from unnamed people, the text says so.
- Will we run out of data? Limits of LLM scaling based on human-generated data (Epoch AI, accessed October 2026)
- Consent in Crisis: The Rapid Decline of the AI Data Commons (Longpre et al., Data Provenance Initiative, arXiv, July 2024)
- Failed companies are selling old Slack chats and email archives to train AI (Gizmodo, citing Forbes, April 2026)
- AI labs are buying data from dead startups to train models (MIT Technology Review, October 2026)
- Reddit says it's made $203M so far licensing its data (TechCrunch, citing Reddit's IPO filing, February 2024)
- Common Crawl (Common Crawl, accessed October 2026)
- AI models collapse when trained on recursively generated data (Nature, July 2024)
- Textbooks Are All You Need (arXiv, June 2023)
- LIMA: Less Is More for Alignment (arXiv, May 2023)
- DataComp-LM: In search of the next generation of training sets for language models (arXiv, June 2024)
- OpenAI wants to work with organizations to build new AI training data sets (TechCrunch, November 2023)
- How AI labs use Mercor to get the data companies won't share (TechCrunch, October 2025)
- GDPval: Evaluating AI model performance on real-world economically valuable tasks (OpenAI, arXiv, October 2025)
- Silicon Valley bets big on environments to train AI agents (TechCrunch, September 2025)
- Gradient Updates: the state of RL environments (Epoch AI, January 2026)
- Exclusive: Reddit in AI content licensing deal with Google (Reuters, via Yahoo, February 2024)
- OpenAI partners with Wall Street Journal publisher News Corp (VentureBeat, citing the Wall Street Journal, May 2024)
- Axel Springer and OpenAI license agreement is worth tens of millions of euros per year (The Decoder, citing the Financial Times, December 2023)
- Shutterstock annual report (Form 10-K) for fiscal 2023 (Shutterstock, SEC filing, 2024)
- Shutterstock annual report (Form 10-K) for fiscal 2024 (Shutterstock, SEC filing, 2025)
- Tech giants are on a billion-dollar shopping spree for AI training data (The Decoder, citing Reuters, April 2024)
- Report: Wiley set to earn $44M from AI rights deals, confirms no opt-out for authors (infoDOCKET, August 2024)
- Stack Overflow and OpenAI partnership announcement (Stack Overflow, May 2024)
- Anthropic authors lawsuit settlement (Boston Globe, September 2025)
- Bitext customer support LLM chatbot training dataset (Hugging Face dataset card, accessed October 2026)
- SWE-bench: Can language models resolve real-world GitHub issues? (arXiv, October 2023)
- The Stack: 3 TB of permissively licensed source code (BigCode, arXiv, November 2022)
- Protege profile and interview with Bobby Samuels (Pulse 2, June 2026)
- Stanford AIMI datasets for commercial use (Stanford AIMI, accessed October 2026)
- Datasheets for Datasets (Gebru et al., arXiv, March 2018, revised December 2021)
- Key contract terms and conditions for AI products and services, part 1: data ownership and licensing (Vorys, August 2023)
- Key considerations when allowing a vendor to train its AI models on customer data (Morgan Lewis, June 2026)
- AI companies: uphold your privacy and confidentiality commitments (FTC Office of Technology, January 2024)
- AI (and other) companies: quietly changing your terms of service could be unfair or deceptive (FTC Office of Technology, February 2024)
- FTC finalizes settlement with photo app developer related to misuse of facial recognition technology (FTC, May 2021)
- Rite Aid banned from using AI facial recognition after FTC says retailer deployed technology without reasonable safeguards (FTC, December 2023)
- FTC takes action against the company formerly known as Weight Watchers for illegally collecting kids' sensitive health data (FTC, March 2022)
- Article 29 Working Party opinion on data processing at work (A&L Goodbody, July 2017)
- ICO guidance overview: lawfully monitoring workers (Freeths, November 2023)
- Overview of new rights for workers under the California Consumer Privacy Act (UC Berkeley Labor Center, accessed October 2026)
- California Penal Code section 632 (FindLaw, accessed October 2026)
- Federal judge allows Google customer service AI class action to proceed (ZwillGen, February 2025)
- Extra large PII-zza: court allows California privacy class action to proceed for use of AI phone call assistant (Squire Patton Boggs Privacy World, December 2025)
- 18 U.S. Code section 1839, definitions (Cornell Legal Information Institute, accessed October 2026)
- Trade secrets and nondisclosure agreements (Holland & Knight, December 2018)
- Federal court addresses trade secret protection when startups pitch to venture capital investors (Faegre Drinker, August 2026)
- Frequently asked questions about the GNU licenses (Free Software Foundation, accessed October 2026)
- GNU Affero General Public License, version 3 (Free Software Foundation, accessed October 2026)
- The MIT License (Open Source Initiative, accessed October 2026)
- Copyright and Artificial Intelligence, part 3: generative AI training (pre-publication version) (U.S. Copyright Office, May 2025)
- Art. 4 GDPR, definitions (gdpr-info.eu, unofficial reproduction of the regulation, accessed October 2026)
- Recital 26 GDPR, not applicable to anonymous data (gdpr-info.eu, accessed October 2026)
- Pseudonymisation (UK Information Commissioner's Office, accessed October 2026)
- EDPB advises on pseudonymisation for GDPR compliance (Hunton Andrews Kurth, 2025)
- Art. 5 GDPR, principles relating to processing of personal data (gdpr-info.eu, accessed October 2026)
- Art. 6 GDPR, lawfulness of processing (gdpr-info.eu, accessed October 2026)
- Opinion 28/2024 on certain data protection aspects related to the processing of personal data in the context of AI models (European Data Protection Board, December 2024)
- Art. 28 GDPR, processor (gdpr-info.eu, accessed October 2026)
- California Consumer Privacy Act of 2018, statute text (California Privacy Protection Agency, version effective July 2024)
- California Consumer Privacy Act (California Attorney General, accessed October 2026)
- US state privacy laws overview (IAPP, updated October 2025)
- 45 CFR 164.514, other requirements relating to uses and disclosures of protected health information (eCFR, accessed October 2026)
- Identifiability of data (Harvard Data Privacy Lab, Latanya Sweeney, accessed October 2026)
- Robust de-anonymization of large sparse datasets (Narayanan and Shmatikov, arXiv, October 2006)
- AOL search log release (Wikipedia, accessed October 2026)
- Estimating the success of re-identifications in incomplete datasets using generative models (Nature Communications, July 2019)
- Microsoft Presidio documentation (Data Privacy Stack, accessed October 2026)
- k-anonymity: a model for protecting privacy (Harvard Data Privacy Lab, 2002)
- NIST SP 800-188, De-identifying government datasets: techniques and governance (NIST, September 2023)
- Guidelines for evaluating differential privacy guarantees, NIST SP 800-226 (NIST, March 2025)
- Extracting training data from large language models (USENIX Security Symposium, August 2021)
- Scalable extraction of training data from (production) language models (Nasr et al., arXiv, November 2023)
- Valuing data assets (Deloitte, December 2025)
- OpenAI and Google are buying YouTubers' unpublished videos for up to $4 per minute (The Decoder, citing Bloomberg, January 2025)
- Off-the-shelf call center audio versus custom (AIxBlock vendor blog, undated)
- AI training dataset market size, share and trends (Global Information, reselling Grand View Research, accessed October 2026)
- Licensing of data for AI model training: things to take note of (Halim Hong & Quek, February 2024)
- AI training data licensing: a usable agreement (terms.law, undated)
- Legal implications in AI development and deployment: training data and grounding data (Sidley Austin, July 2026)
- Key IP licensing considerations in AI (Best Lawyers, August 2026)
- Created by Humans helps authors license their creative work to AI models (TechCrunch, June 2024)
- I want to opt out of my chat being used for model training (Anthropic privacy center, accessed October 2026)
- Your data in the OpenAI API (OpenAI developer documentation, accessed October 2026)
- Vertex AI generative AI data governance (Google Cloud documentation, accessed October 2026)
- SOC 2 audit and assurance (AICPA, accessed October 2026)
- AI Risk Management Framework (NIST, accessed October 2026)
- Samsung employees leaked company secrets via ChatGPT (Security Affairs, April 2023)
- Data Provenance Standards (Data & Trust Alliance, July 2024)
- Zoom updates terms of service after AI training backlash (The Record, August 2023)
- Slack's terms and privacy principles update draws AI training criticism (The Register, May 2024)
- Workplace platform Slack clarifies data policy on AI after online criticism (Euronews, May 2024)
- No AI training in newly distrusted terms of service, Adobe says (Malwarebytes, June 2024)
- Tumblr and WordPress posts will reportedly be used for OpenAI and Midjourney training (Engadget, relaying 404 Media, February 2024)
- 11 U.S. Code section 363, use, sale, or lease of property (Cornell Legal Information Institute, accessed October 2026)
- 11 U.S. Code section 332, consumer privacy ombudsman (Cornell Legal Information Institute, accessed October 2026)
- FTC Chairman Andrew N. Ferguson issues letter on 23andMe bankruptcy impact (FTC, March 2025)
- The FTC addresses 23andMe's bankruptcy (Foley Hoag, March 2025)
- Troveo (Troveo, accessed October 2026)
- Snowflake Marketplace documentation (Snowflake, accessed October 2026)
- AWS Data Exchange (Amazon Web Services, accessed October 2026)
- AI training data marketplaces (Extruct, June 2026)
About the author
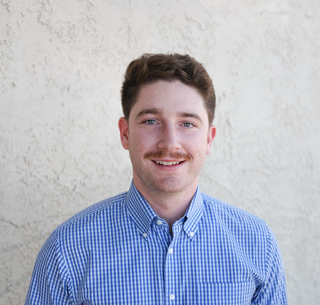
Josh Bernstein is an AI expert and the co-founder and managing partner of SellYourAIData, where he leads buyer relationships and deal strategy. He works with AI every day: he builds the AI agents, large language model content systems and data pipelines that run Something Inc., the SEO and AI search agency he co-founded, which has served more than 95 companies. His focus there is how AI models find, read and cite company information, which is the same question AI buyers ask when they license data. Before that he spent more than ten years running search and growth programs for B2B technology, SaaS, ecommerce and Fortune 500 brands.
- Co-founder and Managing Partner, SellYourAIData
- Co-founder, Something Inc. (SEO and AI search, 95+ companies served)
- Builds AI agents, LLM content systems and AI search visibility tools
- 10+ years in search and growth for B2B and Fortune 500 brands
 Appenvs
 Toloka